keymem


The associative memory layer for LLM agents — recall by association, not just similarity.
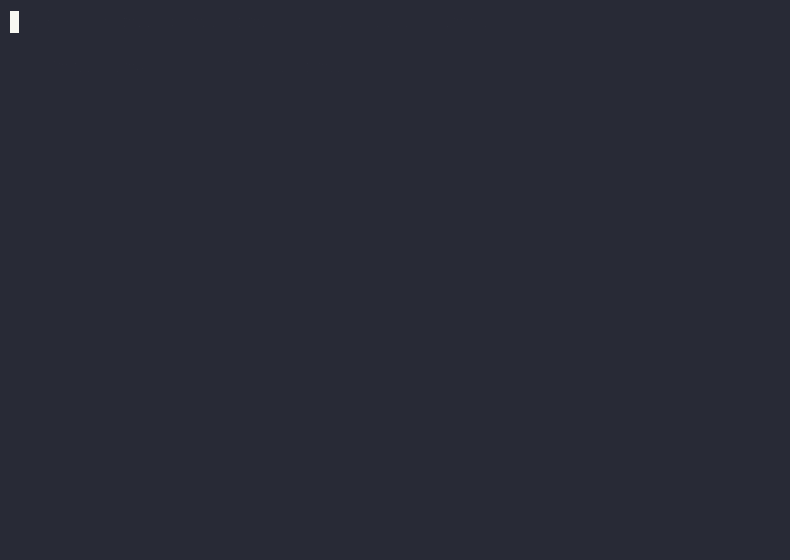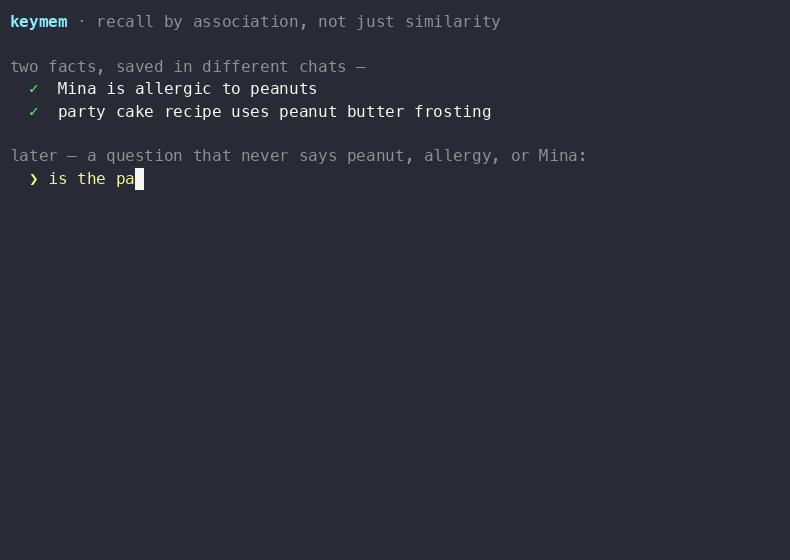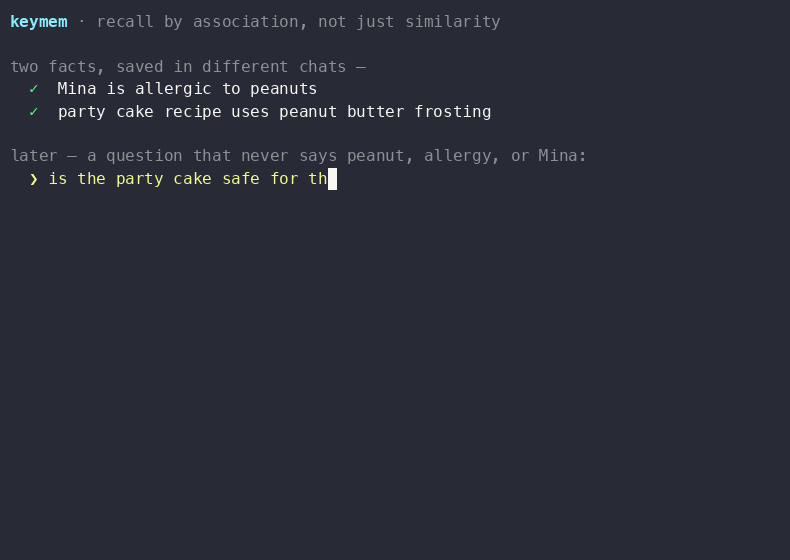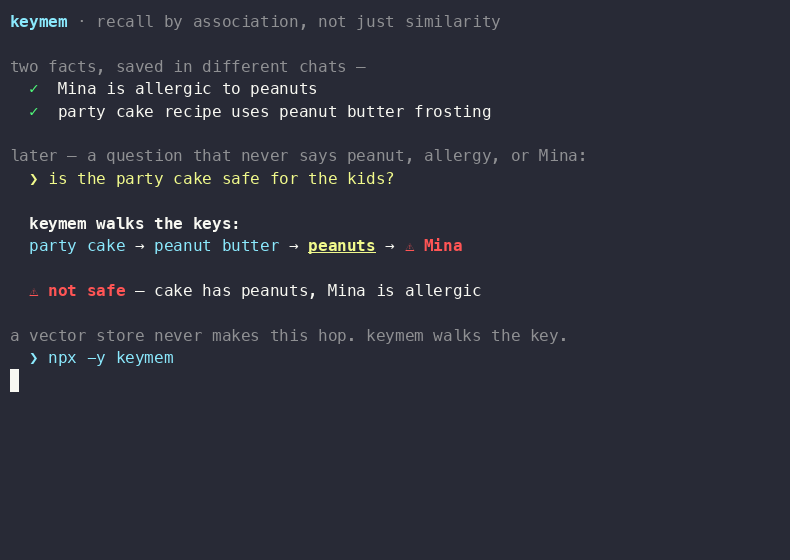
Most agent memory is a vector store. It surfaces what sounds like your query — and misses everything your query is connected to.
keymem stores memories in a key graph instead. A search for "Newton" can still reach "strawberries" — Newton → apple → fruit → strawberry. The path lives in the graph, not in embedding space. It runs locally as an MCP server, so any MCP-compatible agent gets human-like associative recall with no external database.
Works with: Claude Desktop · Claude Code · any MCP-compatible LLM agent
Why associative memory?
Vector-store memory retrieves by embedding similarity. That works until the thing you need isn't similar to the words you typed:
Query: "Newton"
Similarity search finds: "Newton discovered gravity"  ✅
Similarity search misses: "user likes strawberries" ❌A person makes the leap anyway — Newton reminds them of the apple, apples are fruit, they like strawberries. keymem makes that same leap because the path exists in the key graph: Newton → apple memory → fruit key → strawberry memory. No embedding distance connects "Newton" and "strawberry"; a chain of shared keys does.
This is the core idea: memories are not islands ranked by distance. They are nodes in an N:M key/value graph that an agent can walk.
How it works
Key Space (concepts)         Value Space (memories)
[apple]   ────────┬─────────→      ↑ same memory
[gravity] ────────┘
                  │
[apple]   ────────┼─────────→ "apples are red fruit"
[fruit]   ──────┬─┘
[red]     ──────┤
                │
[fruit]   ──────┼─────────→ "user likes strawberries"
[strawberry]────┘Memories live in a Value Space, reached through a separate Key Space — one memory reachable via many keys, one key leading to many memories.
recall("Newton") returns matching key clusters such as [Newton] and [apple], not memory content. The agent then navigates explicitly: read_key(apple) → select the Newton memory → read_memory(...) → discover its [fruit] key → read_key(fruit) → select the strawberry memory.
The default MCP flow is therefore Key → Memory → Key. Full memory content enters the model context only when the agent deliberately calls read_memory() — so broad concepts never flood the context window.
Quick Start
keymem is an MCP server (a CLI), not a library. Run it with
npx -y keymem(recommended — always the latest) or install the command globally withnpm i -g keymem. Do not add it to your app withnpm i keymemas a dependency: it bundlesopenai,zod, and the MCP SDK, so inside an existing project it just duplicates those trees (and can clash with your app'szod/openaiversions). Thenpm i keymemline npm shows on the package page is for libraries — it doesn't apply here.
# Optional global install (npx needs none). This puts a `keymem` command on PATH that
# MCP clients can spawn. Run bare, it starts a stdio MCP server and waits for a client —
# so point your MCP config at `keymem` (or just use `npx -y keymem` as shown below).
npm i -g keymemClaude Desktop
Add to claude_desktop_config.json:
OpenAI embeddings:
{
  "mcpServers": {
    "keymem": {
      "command": "npx",
      "args": ["-y", "keymem"],
      "env": {
        "OPENAI_API_KEY": "your-openai-api-key"
      }
    }
  }
}Local embeddings (no API key required) — bge-m3 recommended:
{
  "mcpServers": {
    "keymem": {
      "command": "npx",
      "args": ["-y", "keymem"],
      "env": {
        "EMBEDDING_BACKEND": "local",
        "LOCAL_EMBEDDING_MODEL": "bge-m3"
      }
    }
  }
}
bge-m3(multilingual, recommended) auto-downloads ~570MB on first run, then caches. OmitLOCAL_EMBEDDING_MODELfor the lighter default (fast-multilingual-e5-large). Add"KEYMEM_RERANK": "true"to enable cross-encoder reranking (downloads a second model on first use).
Plugin (recommended — Claude Code & Codex)
The repo is also a plugin marketplace, so one install wires up everything: the MCP server
(daemon-backed shim), the UserPromptSubmit hook that passively surfaces related memories on every
prompt, and the keymem skill carrying the recall/remember protocol.
Claude Code:
/plugin marketplace add donggyun112/keymem
/plugin install keymem@keymemCodex CLI:
codex plugin marketplace add donggyun112/keymem
codex plugin add keymem@keymemCodex prompts once to trust the hook; approve it or the push path stays silent. The plugin defaults
to local bge-m3 embeddings (auto-downloads ~570MB on first run, no API key). For OpenAI
embeddings, use the manual setup below instead — plugin MCP servers only see the env they declare.
Claude Code (manual)
# OpenAI embeddings
claude mcp add keymem -e OPENAI_API_KEY=your-key -- npx -y keymem

# Local embeddings (no API key required) — bge-m3 recommended (auto-downloads ~570MB on first run)
claude mcp add keymem -e EMBEDDING_BACKEND=local -e LOCAL_EMBEDDING_MODEL=bge-m3 -- npx -y keymemCodex CLI (manual)
# OpenAI embeddings
codex mcp add keymem --env OPENAI_API_KEY=your-key -- npx -y -p keymem keymem-shim

# Local embeddings (no API key required)
codex mcp add keymem --env EMBEDDING_BACKEND=local --env LOCAL_EMBEDDING_MODEL=bge-m3 -- npx -y -p keymem keymem-shimUse the keymem-shim entry point (not bare keymem): it runs the shared daemon the push-path hook
talks to. For the hook, add to ~/.codex/config.toml:
[[hooks.UserPromptSubmit]]
[[hooks.UserPromptSubmit.hooks]]
type = "command"
command = "node /absolute/path/to/keymem/hooks/keymem-hook.mjs"
timeout = 5Codex only forwards the env vars declared in its MCP entry, so pass every KEYMEM_* /
SUPER_MEMORY_* override with --env.
That's it — recall and remember work immediately. The agent calls recall before its first reply, navigates with read_key/read_memory, and saves with remember.
For reliable proactive saving in Claude Code, add the following to ~/.claude/CLAUDE.md (MCP prompts are not automatically applied as persistent Claude Code instructions):
## keymem

- Before the first reply and whenever the topic changes, call `recall` silently with short noun-keyword queries.
- Before ending every reply, check whether this turn revealed a durable fact: a name, preference, decision, correction, project fact, or goal.
- If it did, call `remember` or `remember_batch` silently in the same turn with 3-6 diverse keys. A durable fact left unsaved is a bug.
- Use `correct` when existing information changes. Save nothing only when the turn revealed nothing durable.
- Never mention memory lookup or saving to the user.In Codex, put the same block in ~/.codex/AGENTS.md. (The plugin install ships this as the keymem
skill instead, so you can skip it there.)
For other MCP clients, include the memory_system_prompt MCP prompt in the agent's persistent system instructions.
Manual / Development
git clone https://github.com/donggyun112/keymem
cd keymem
pnpm installCreate .env:
OPENAI_API_KEY=your-openai-api-key
OPENAI_EMBEDDING_MODEL=text-embedding-3-smallOr use local embeddings (no API key required):
EMBEDDING_BACKEND=local
LOCAL_EMBEDDING_MODEL=fast-multilingual-e5-large # default; best fit for Korean/multilingual keyspnpm dev
# or:
pnpm build
pnpm startRequirements:
- Node.js 20+
- pnpm for local development
- OpenAI API key for OpenAI embeddings, or
fastembedfor local embeddings
Features
- N:M key/value graph — memories and the concepts that index them are separate spaces, linked many-to-many. One memory is reachable through many keys; one key leads to many memories.
- Agent-driven Key → Memory → Key navigation — the agent walks the graph deliberately instead of collapsing it into one opaque similarity search.
- Associative multi-hop recall — reach memories no embedding distance would connect, by following chains of shared keys.
- Depth system — every memory has a stability score
0.0 → 1.0. Frequently recalled facts deepen, stabilize, and decay slower. - Versioning, not overwriting — corrections preserve the full history (when a belief changed, and from what).
- Key types —
conceptkeys match by similarity;name/proper_nounkeys match exactly, so "동건" never matches "뉴턴" just for being short. - Cross-lingual key merging (IDF) —
파이썬andPythoncollapse into one canonical cluster instead of fragmenting the key space. - Hebbian link learning — the path an agent actually traverses gets reinforced ("fire together, wire together"), so useful associations become easier to reach.
- Hybrid retrieval (optional direct mode) — BM25 + dense + Reciprocal Rank Fusion, with depth/time modulation and configurable multi-hop expansion.
- Cross-encoder reranking (opt-in) —
bge-reranker-v2-m3re-scores candidates in direct mode. - Local-first — all data in a local JSON graph; no external database. OpenAI or fully-local embeddings (auto-downloaded).
Depth System
Every memory has a depth score 0.0 → 1.0:
| Stage | Depth | Behavior |
|---|---|---|
| Shallow | < 0.3 | Recent, unverified. Easy to update or forget. |
| Medium | 0.3–0.7 | Confirmed multiple times. Stable. |
| Deep | > 0.7 | Well-established fact. Resists correction. |
Depth increases +0.05 only when the agent confirms a fact with read_memory(). Key search, read_key(), and passive inject:true previews do not deepen memories. Deep memories decay slower over time. If you try to correct a deep memory, it resists — its depth stays higher even after supersede.
Key Types
Not all keys should behave the same. Names shouldn't match semantically — "동건" shouldn't match "뉴턴" just because they're both short Korean words.
| Type | Matching | Use Case |
|---|---|---|
concept (default) | Embedding similarity ≥ threshold (0.28 OpenAI / 0.60 local) | Topics, categories, attributes |
name | Exact match only | Person names |
proper_noun | Exact match only | Brands, places |
Name/proper_noun keys also get an IDF penalty (×0.5) when they become hub keys connected to many memories, preventing them from polluting unrelated searches.
Versioning (not overwriting)
"user lives in Seoul"   (depth: 0.4 → weakened to 0.12, preserved)
        ↑ superseded by
"user moved to Busan" (depth: 0.0, new)keymem keeps the full history instead of overwriting on change. Every correction is traceable — when did the belief change, and from what session?
Key Merging
Add key "파이썬"  → finds existing "Python" (similarity 0.87 > threshold 0.85)
→ reuses existing key instead of creating duplicatePrevents key space fragmentation. The same concept across languages or phrasing stays unified.
Agent-driven Retrieval (default)
The default MCP API keeps Key Space and Value Space separate:
recall(query)searches canonical keys and aliases. It returns key IDs, concept labels, match scores, linked-memory counts, hub status, and specificity — never memory content.read_key(key_id)returns ranked memory IDs and metadata, never content. Hub keys are paginated withlimit/offsetso broad concepts cannot flood context.read_memory(memory_id, via_key_id)returns the full memory plus every connected key
…